The part that was actually hard
Scraping two sites is the easy half. The half that decides whether a watcher is worth having is identity: what makes two scraped rows the same posting across runs. Get it wrong in one direction and the same listing arrives by email every hour; wrong in the other and a genuinely new posting is swallowed as a duplicate.
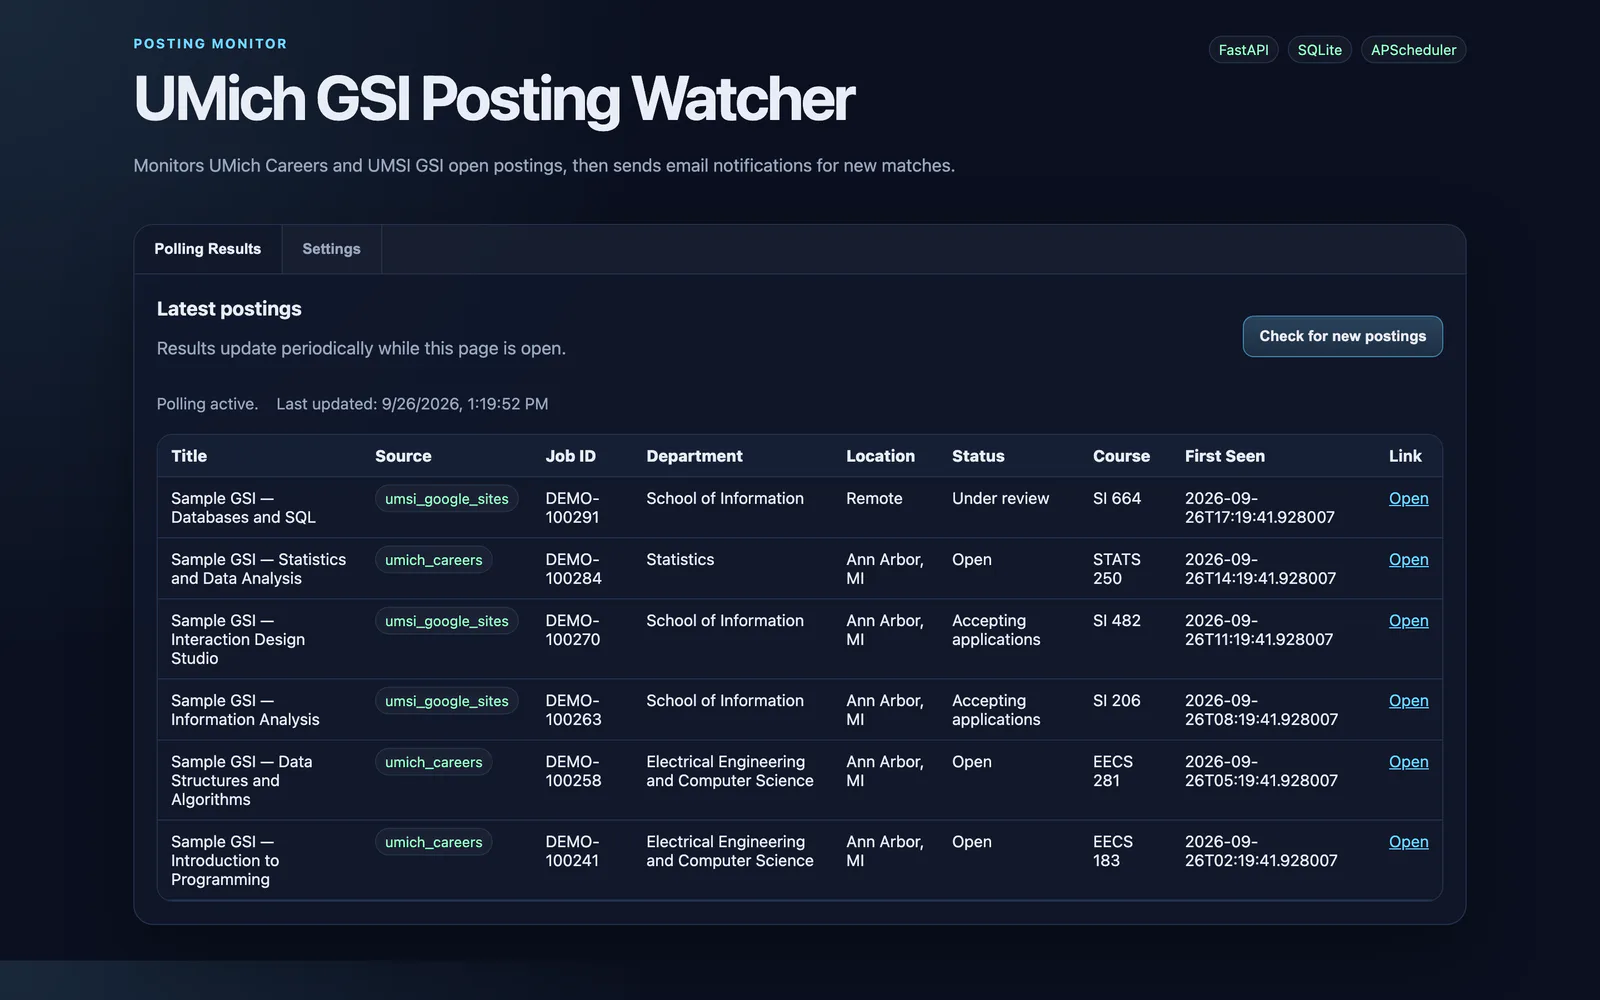
The answer here is a stable key derived from the job opening ID where the source publishes one and from the URL where it does not, held in SQLite alongside a first-seen timestamp. That is the piece that survives whatever the transport turns out to be, and it is the reason the results table can say when it first saw something rather than only that it is there now.